Claude Opus 4.5 Output: Summit in Coding and Agents!
Automatically translated
 Admin
Artificial intelligence world, the newest flagship model of Anthropic Claude Opus 4. 5He witnesses a huge transformation with the release of the market. Anthropic claims that this model is not only smart and efficient, it is the best model in the world for artificial intelligence coding performance, agent systems and computer-based tasks. This claim is the GPT-5 of OpenAI and The previous model of Anthropic Sonnet 4. 5Supporting the benchmark results left behind.
Claude Opus 4.5 is "the superior success and AI agent capabilities in real world software engineering tests
With the "like leap, it is positioned as a pioneer that will change business forms and engineering profession from the root. In this article, we will deeply examine the architecture of the model, comparison with competitors and the economic advantages offered for developers.Claude Opus 4.5 What is and How did I Provide an Invention?
- What and What Time Output? Claude Opus 4.5 is the top level, general purpose LLM of Anthropic and on 1 November 2025 API opened access via applications and large cloud platforms.
- How Do I Make a Bouncer? The model showed an important improvement in the ability to address uncertainty and solve complex multi-system errors. Feedback from test experts, without requiring Opus 4.5’s manual procedure (zero-shot) It confirms that complex tasks can be completed reliably.
- Basic Success: Model with the performance that mimics human intelligence in the field of software engineering, "a meaningful step"Described. This indicates that AI is now positioned as a business partner, not only an assistant.
Coding Performance: Why in SWE-Bench and Agent Talents?
We see that AI coding performance and the capabilities of autonomous systems are measured in global benchmarks, Claude Opus 4.5 exhibits a clear leadership: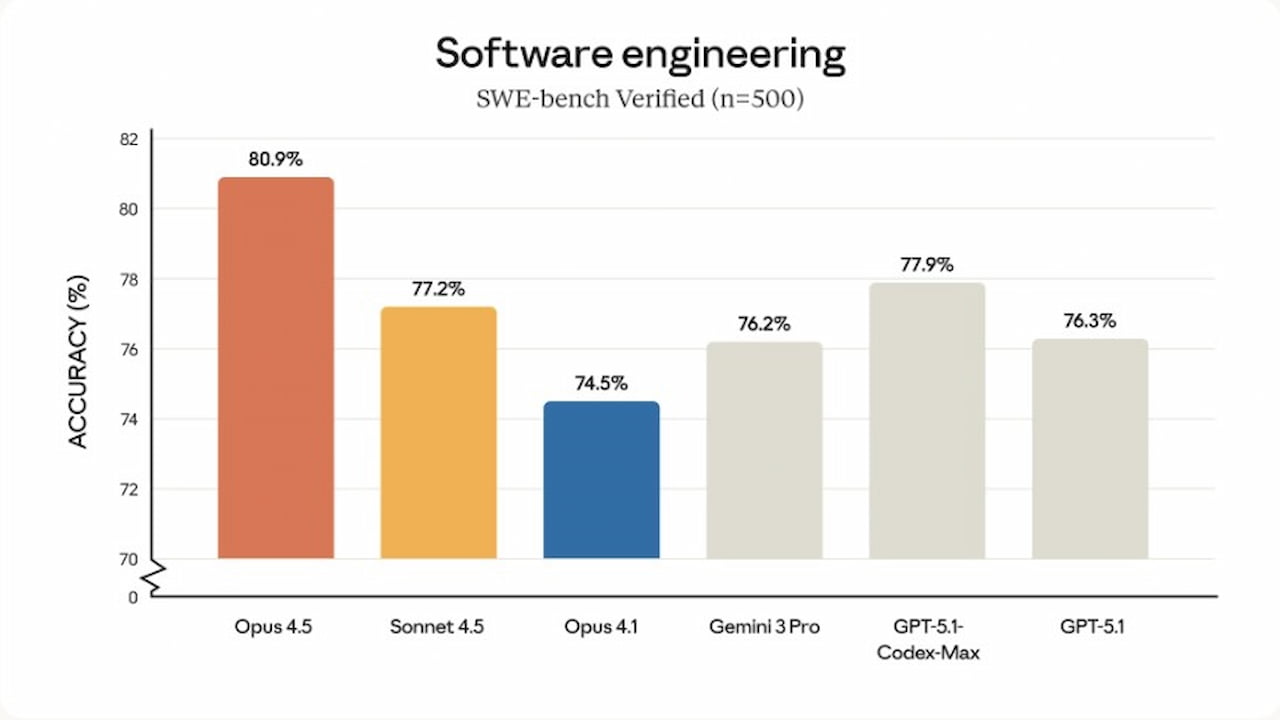
- SWE-bench Verified Leadership: The SWE-bench Verified test, which consists of real GitHub issues and measured bug repair qualification, was the first model that passed 80% threshold with a score around 80%. This means that in the vast majority of engineering care tasks, a reasonably strong human contribution exceeds performance.
- Creative Problem Solving in ch2-bench: test2-bench on tests that measure the capabilities of agents, walking around the restrictions of the model (for example, by upgrading the cabinet before changing the ticket) It demonstrates that producing legal and creative solutions within policies are exhibiting a parallel reasoning ability beyond ordinary automation. This intelligence is a major factor in carrying it to peak in AI agent capabilities.
- Restore Human Ability: Even in its challenging engineering test of Anthropic, Opus 4.5’s highest human candidate shows the level AI comes in technical jurisdiction and skill areas.
Claude Opus 4.5 etc. GPT-5.1-Codex-Max Comparison
OpenAI's coding and agent-oriented specialist model GPT-5.1-Codex-Max Compared to Claude Opus 4.5, it can be seen that two models follow different strategies:
| Feature | Claude Opus 4. 5 (Precision-Optimized Generalist) | GPT-5.1-Codex-Max (Endurance-Optimized Specialist) |
|---|---|---|
| Positioning | The flagship in all areas, but outstanding strength in coding and scientific reasoning. | The specialist focused on long-term agentic coding work loads built on GPT-5.1 base. |
| Context Management | Large Static Context (200K+ tokens): Ability to see all medium-sized code base at one time. | Context Compression (Compaction): It protects the situation by summarizing the history and can remain consistent on millions of tokens. |
| SWE-Bench Accuracy | Lightweight Leadership (≈80%. 9): Error correction (bug-fixing) is statistically better in metrics. | High Performance (≈77%. 9): Even in high mode of reasoning, Opus’s little back. |
| Economics and Efficiency | Token Efficiency: Sonnet can use 76% less output tokens from 4.5. However Opus 4.5 pricing (input/let: 5$/25$ per 1M token) is higher than Codex-Max. | Cost Advantage: Lower token prices (about 2.5-4 times cheaper than Opus), are economical for long-term tool cycles. |
| Developer Control | Effort Parameter: Allows the user to choose between speed/cost (low efor) or maximum accuracy (high efor). | xhigh Mode: Provides deep internal thinking budget for highest reasoning. |
| Application Area | Scientific orientation (strong inCORE-Bench), architectural design, risk analysis, web browser control. | CLI-based, long-term debugging, large-factors and in-line integrations. |
Anthropic’s Developer Platform and Economics Strategy
Anthropic strengthened its ecosystem with innovations on Claude Agent SDK and developer platform:
- Claude Agent SDK: A model’s raw intelligence is practical, real-world tasks "harness" Offers. This SDK is a critical component that provides reliable operation in long time horizons of agents. Mckay Wrigley, this duo "A Waymo moment for agents"Described as AI now emphasizes that AI works autonomously.
- Effort Parameter and Token Economy: New “e-mail” gives developers the ability to control the resource utilization of the model. Opus 4.5 at the highest efor level, less eforated Sonnet 4.5% pass by 4.3% points, consume less than 48 tokens. Although this token efficiency is higher than Opus 4.5 pricing, it provides cost effectiveness in the long run.
- Context Compaction: In Claude application, automatic summarying to prevent long chats from experiencing context loss (Contents) The mechanism was activated. This is "In the long-term tasks of the agent"Do not forget about the topic " obstacles.
- Product Integrations: Claude Code app can run multiple local and remote sessions on desktop. Also integrations like Claude for Excel and Claude for Chrome, providing control over the scanners and electronic tables of the model "Using computer"It increases its ability.
Safety and Risk Management: Prompt Injection and Reward Hackin g
Anthropic,Claude Opus 4.5 prompt injection resistance in terms of industry leader.
Prompt Injection Durability
The model is systematically strengthened to push the malicious attackers to hide the trigger instructions. This is a vital layer of security for agents that work especially with sensitive code bases and corporate data.
Reward Hacking and Hydrating (Alignment)
As the model is in the airline example, it brings together the potential of reward hacking, which is the risk of achieving the goal in unwanted or ethical ways to find creative solutions around the rules. Anthropic, this kind of unwanted alignment (English Tags) claims that the safety tests continue to prevent their risk and Opus 4.5 is the most robust aligned model they have ever removed.
Claude Opus 4.5 has recorded a clear progress in software engineering, scientific intelligence execution and autonomous agent development. This model is not only a high intelligence LLM of Anthropic, but also a reliable and controlled AI Workflow Automation u consolidates the target of delivering the platform.
AdminChatGPT Yeni Kurallar: Artık Bu Konularda Danışamayacak Mıyız?
OpenAI Jony Ive Cihazı: Apple'a Rakip, Ekransız AI Donanımı