DeepSeek R2 Comes: Efficiency Revolution in AI without Nvidia
Automatically translated
 Writer
DeepSeek R2, expected to be used in the next months, is one of the strongest examples of new generation architectures that aim to reduce hardware dependence in the AI field in 2026. With DeepSeek R1, this approach represents a tactical change in the center of AI training methods, artificial intelligence efficiency and cost optimization.
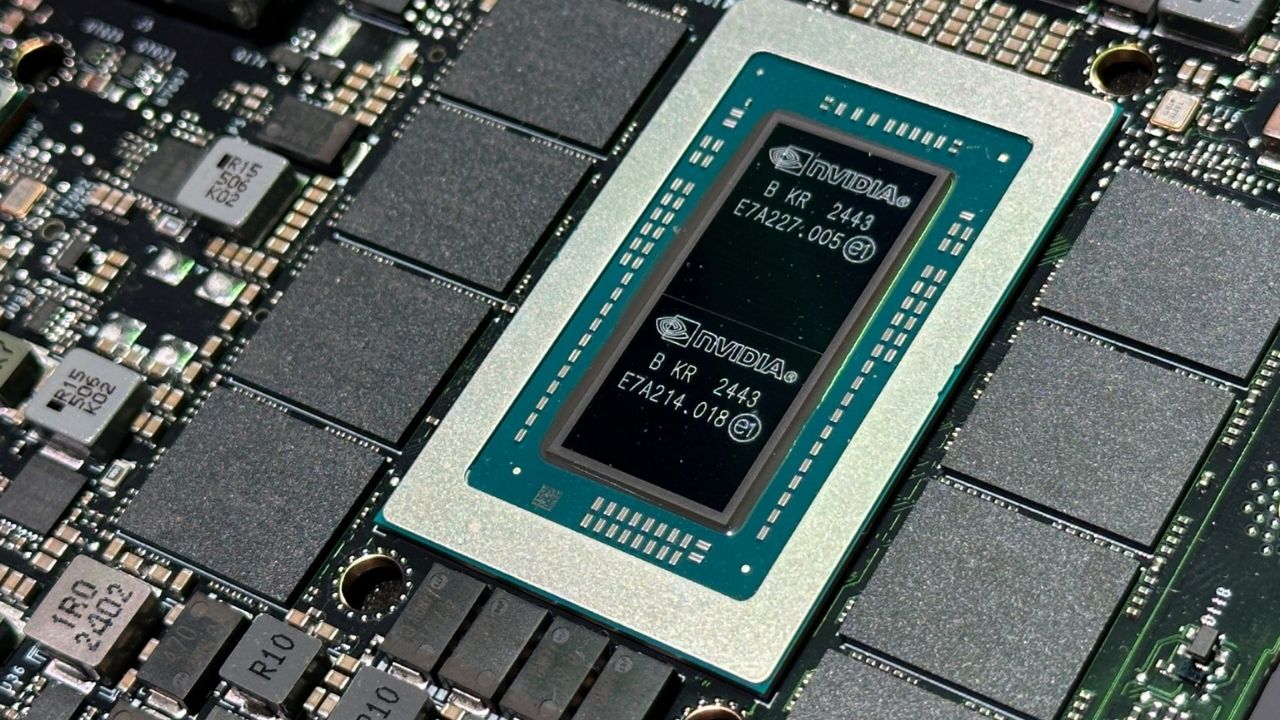
Nvidia chip attack caused a serious supply pressure in the AI ecosystem, DeepSeek R2 appeared as a strategic solution not only from the technical direction for performance competition with less hardware needs.
Low Cost AI Formula: Manifold-Constrained Hyper-Connections
As a distinctive element of DeepSeek R2 architecture, Manifold-Constrained Hyper-Connections stands out. This approach, which offers a more selective and context-conscious parameter interaction compared to classically connected structures, reduces the material load by allowing the relationship between only linked sample space. Artificial intelligence efficiency with DeepSeek R2 thanks to this structure only inference not in the stage, it is the basis of educational architecture. The contribution of this structure in general to artificial intelligence efficiency can be presented as follows:
- Block unnecessary information flow
- Low GPU memory consumption Home
- More stable and predictable training process
DeepSeek R2, Chat GPT and Google Gemini Racing
DeepSeek R2 is a top level LLM developed with the mixture-of-Experts architecture on the previous DeepSeek R1 nesli. Especially in solving technical and logical problems, ambitious results are preached. In Chinese local benchmarks such as C-Eval It is noted that the accuracy scores in 90% levels are achieved. This also indicates that the model is at GPT-benzeri level in theory. But these figures are not yet approved by independent benchmark sets.
Models such as ChatGPT-4 provide reliable results in academic knowledge and overall NLP tests. For example, in comparisons with DeepSeek in meta analysis, the overall information accuracy of ChatGPT is slightly higher and more stable in mathematical problems. However, ChatGPT’s up-to-date news and current information accuracy have been determined to produce serious errors and incorrect information. Google Gemini gives accurate answers to visual and text queries thanks to its multifunctional capabilities and wide context. Versions like Gemini Ultra in Benchmarks general information and accuracy tests is the most leading place. It also offers high accuracy thanks to access current events with real-time internet information integration.
On the other hand, DeepSeek has reports in some audits especially in the direction of news accuracy and low performance in real world content. These types of results show that DeepSeek may encounter original knowledge and reliability issues.
In summary, DeepSeek R2 theoretically promises strong technical and domain-specific accuracy and especially if the benchmark tests stand out, ChatGPT offers a balanced accuracy in terms of general information and consistent language flow. Google Gemini is a number that has become in the current context with real-time information.
Now, the reliability of DeepSeek shows variableity according to the test set and binding. It will be wrong to make a precise assessment without further and independent assessments.
What is Infrastructure Optimization? Will I Fix Stability Problem?
At the beginning of the problems encountered in 27 billion parameters, stability problems arise during education and inference. DeepSeek R2 has integrated infrastructure optimization directly into architectural design for this solution. Layer-based for healthy integration AGC (adaptive grade clipping) With dynamic rescale mechanisms and hardware awareness design, optimization is provided. Thanks to these optimizations, DeepSeek R2 offers high stability in production with lower hardware requirements compared to high parameter models.
AI Economy in 2026: Can Software Power Close Hardware Deficiency?
2026 will be a year in the optimization of not only those who have the most powerful hardware in AI economy, but also successful software and architectural investment. DeepSeek R2 is viewed as one of the results of this conversion. In this context, DeepSeek R2 is the nature of being a sustainable AI economy, not only a technical success.
Economic and technical results
- AI training methods have become more modular.
- Efficient architectures are preferred instead of large parameter models.
- Nvidia chip crisis transformed software optimization into strategic advantage in AI market.
Nvidia Survival Under Ambargosu: China's AI Strategy
Nvidia chip attack is a serious restriction especially for Chinese-based initiatives in AI field. But Liang Wenfeng and its team, known as even behind Deepseek, has made the opportunity for architectural innovation rather than seeing these restrictions as a lack of hardware. This strategy shows that China’s AI ecosystem strengthens its sustainable growth model, rather than trying to maintain hardware import. Basic components of the new strategy; smaller batch size stable training can be sorted as adaptive learning rates, which shortens independent scalable software layers and training time from hardware.
DeepSeek R2, The efficiency-oriented approach started with DeepSeek R1 shows concretely that the software architecture in the 2026 artificial intelligence ecosystem can pass through the hardware. Multi-language support is also new model from DeepSeek R1. Manifold-Constrained Hyper-ConnectionsThis strategy, which is applied due to optimized AI training methods and chip attack; this new model step of China-based company makes DeepSeek R2 an advanced model seems to be based in the US and Nvidia.
| Feature | DeepSeek R1 (Old) | DeepSeek R2 (New/Tahmin) |
| Main Technology | Low Cost Reason g | Hyper-Connection / Manifold Constrained |
| Hardware Need | High Efficiency | Ultra Low Energy / Optimization |
| Launch Date | 2025 | 2026 February (Spring Festival) |
| Rank Target | Top 15 (LiveBench) | Top 5 Goals |
WriterGüney Kore Yapay Zeka Yasası Yürürlüğe Girdi: İşte Detaylar
AId Core Solutions: Yerli Sağlık Teknolojilerinde Yeni Dönem