Falcon-H1R 7B: New Generation LLM Artificial Intelligence Model Stage
Automatically translated
 Writer
While the competition in open source ecosystems is angry every passing day, the Falcon-H1R 7B model stands out as a remarkable alternative. This model optimized for both local installations and corporate applications has 7 billion parameters.
It focuses on ease of installation from capacity quantity in recent periods, hardware properties and real world performances. Falcon-H1R 7B is a model designed to respond to these expectations. It also targets high accuracy in areas such as code typing, abstracting, multi-step intelligence execution and corporate data analysis.
Technical Specifications of Falcon-H1R 7B
AaUppercaseBuilt on transformer-based architecture. Text production is targeting high accuracy rate in tasks such as abstracting, question-cevap, code writing. The model can work with lower memory capacity thanks to its optimized mechanism.
Technical specifications;
- 7 billion parameters
- Improved attention optimization u
- Can Work With Low VRAM
- Structure suitable for local inference performance
- Fine-tuning support
Thanks to these features, Falcon-H1R 7B can easily use both individual users and small medium businesses.
How to Install Falcon-H1R 7B?
Falcon-H1R 7B installation has a highly manageable structure for users with technical infrastructure. Of course, the correct configuration is critical to performance.
- Hardware Setup: When recommended at least 16GB Ram(bell) on the computer, 8 Gb Vram is recommended on the screen card side. Seeing this hardware now features that can be found easily on average computers.
- Environment Installation: Phton should be installed in version 3.10 or higher version. Then PyTorch or similar framework should be installed. Cuda compatibility should be checked if the screen card is for acceleration.
- Model Download: Such files can often be derived from open source platforms such as Hugging Face. Then it is installed via the library.
When installation is completed, the Falcon-H1R 7B will work as a local system without requiring internet connection.
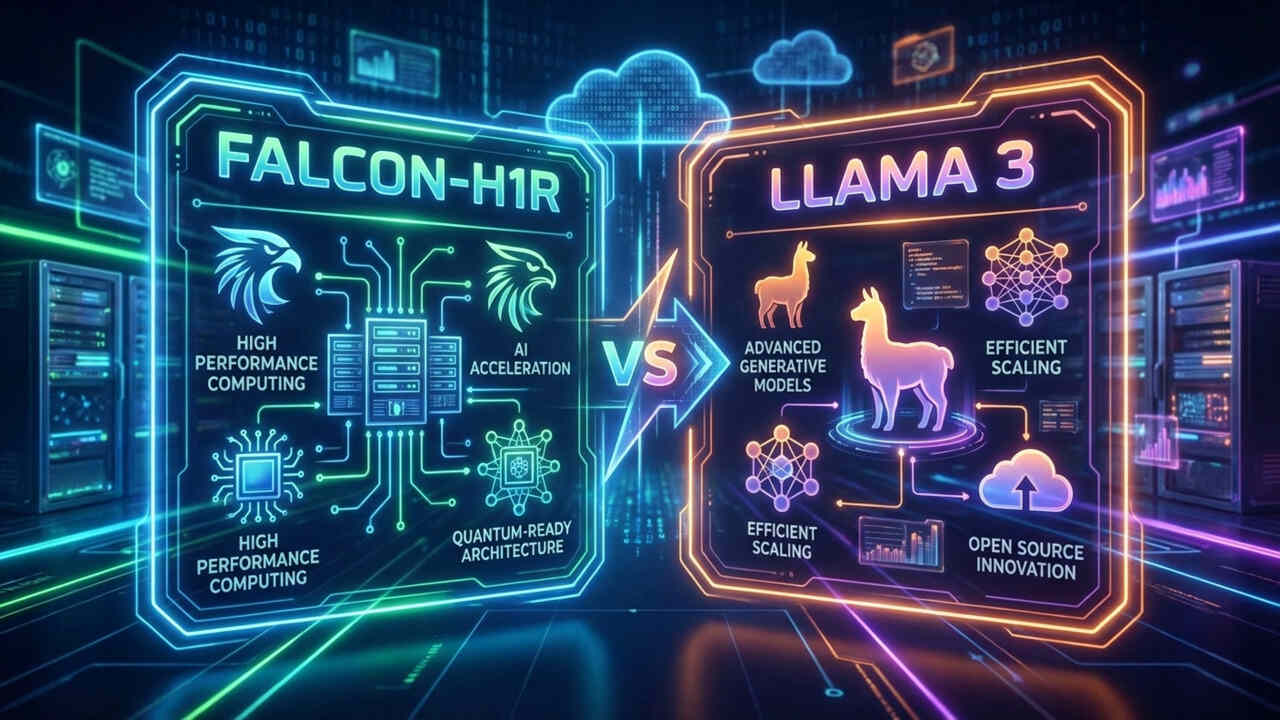
Falcon-H1R vs Llama 3: Performance Comparison
| Criteria | AaUppercase | Llama 3 |
|---|---|---|
| Parameter Number | 7 billion | 8B, 70B (and above variants) |
| Architecture Structure | Optimized transformer | Advanced transformer (Meta optimization) |
| Hardware Requirements Home | Medium level GPU (8–12 GB VRAM enough) | High level GPU/server for 8B, 70B |
| Memory Consumption Home | Lower VRAM usage | Parameter increasing high VRAM requirement |
| Local Installation Convenience | More accessible and light | More complicated for large models |
| Quantization Support | 4-bit / 8-bit works efficiently | Supports but still consume high welding in large models |
| Inference Speed | Low Radius, stable performance | Higher accuracy in large models, more processing time |
| Fine-Tuning Cost | Lower hardware cost Home | Cost increases in large variants |
| Edge Deployment Tags | More convenient | Limited (except small variants) |
| Corporate Use | Ideal for SME and local data analysis | Strong in large-scale enterprise projects |
| Benchmark Performance | Balanced and optimized Tags | Higher score in higher segment variants |
LLM Artificial Intelligence Trends and Location of Falcon-H1R u
In 2026 Home Three main trends in the field of artificial intelligence stand out; local model operation, model optimization and corporate customization. We can say Falcom-H1R 7B is particularly a strong position in two titles. Thanks to its light architecture, it can work smoothly on a device.
On the other hand, hybrid architectures such as Hybird Transformer-Mamba are critical for models in the Falcon-H1R 7B segment. This approach is a mixture structure that combines Mamba-based state space(durum space) models with the advantage of efficiency. Thus, LLM aims to optimize performance and efficiency balance in the field of artificial intelligence.
Mamba architecture linearly processes the sequence data flow, meaning plane complexity. This provides serious performance increase in long- context arrays. The features of Hybird Transformer-Mamba architecture can be said that lower memory consumption affects such as high efficiency, lower latency and hardware-friendly structure in long secretions. Of course, there are scenarios that this approach can not offer contextual relationship modeling alone.
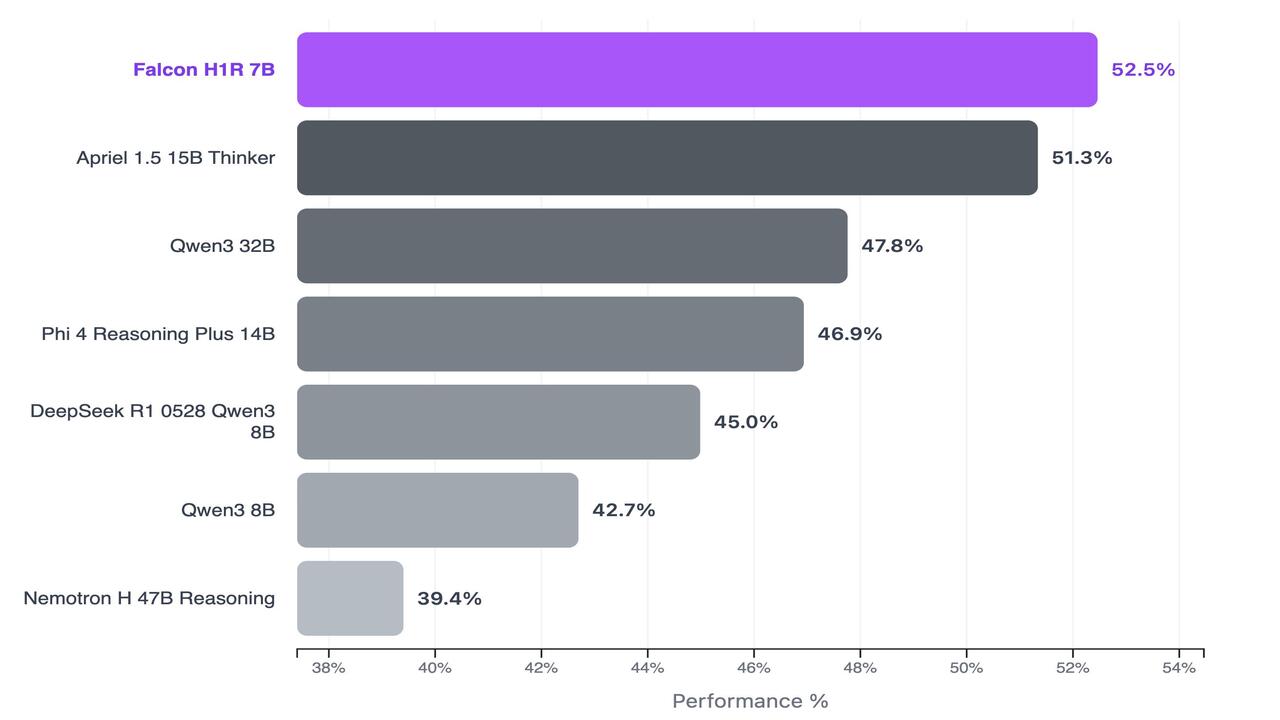
Future Perspective: Efficiency Focused LLM Period
Only parameter size is not enough in LLM race. In 2026, efficiency and hardware optimization are also at the beginning of the subjects that are deducted above. Falcon-H1R 7B is positioned as one of the representatives of this conversion. This model provides sustainable LLM solutions for corporate and cobies while combining high performance with hardware saving. In the coming period, LLM will shape the market by offering more accessible and customizable solutions. Falcon-H1R draws attention as a member of the new paradigm.
WriterGPT-5.4: OpenAI’nin Yeni Nesil Yapay Zeka Modeli
Alibaba, Quark AI Adlı Yapay Zeka Destekli Gözlüğü Tanıttı