New Revolution from Meta: Sam Audio Artificial Intelligence Model!
Automatically translated
 Admin
Meta AI is a great echo in image processing world "Segment Anything ModelBy stimulating the architecture of " (SAM) into the sound world, he launched a new paradigm in the AI ecosystem. SAM Audioaims to change digital audio processing standards from the root with the ability to identify, separate and isolate audio objects in complex acoustic environments. This model is addressed as an independent "obje" of each audio element inside a audio record, just as it can choose every object in a photo.
What is SAM Audio?
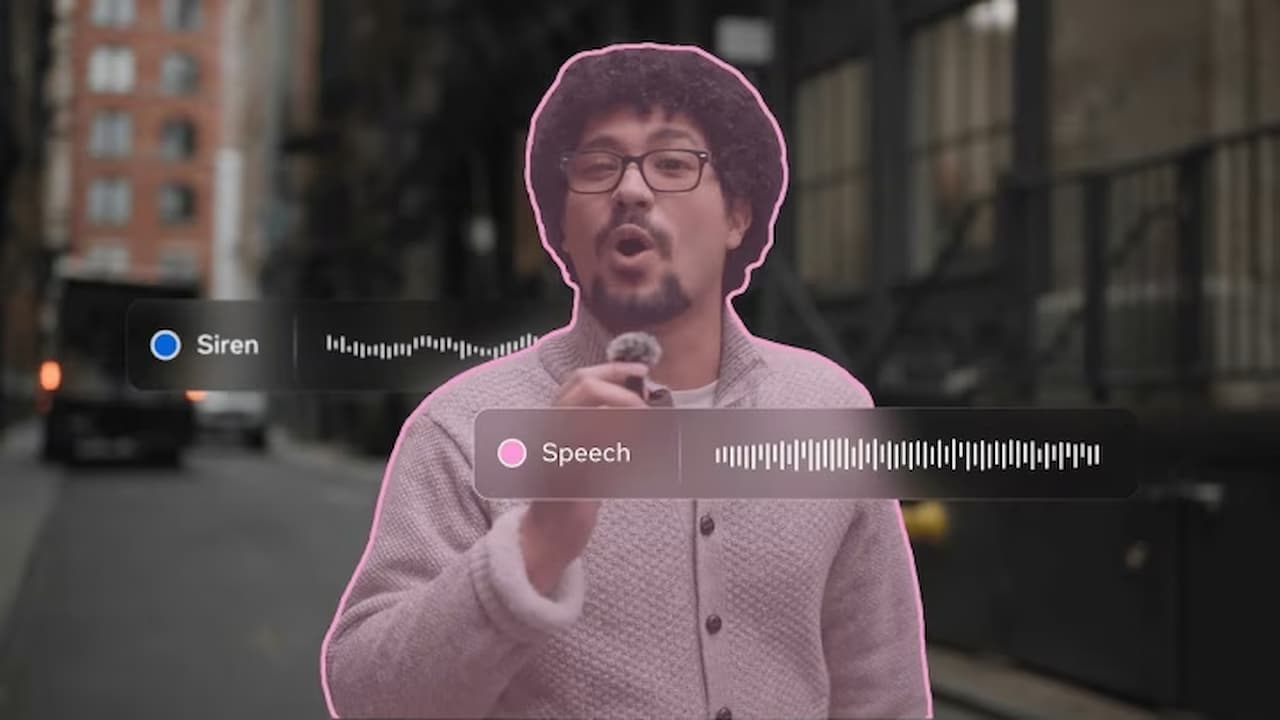
SAM AudioEach audio source (human voice, instrument, animal voice, mechanical noise, etc. in complex and very voice environments. ) is a basic model of artificial intelligence that identifies independently as a "visual object" and perfectly distinguishes them from each other. Unlike traditional audio editing software, this model sound not only as a waveform, each one sees the combination of parts with different characters. This situation gives users the freedom to cut and paste parts of a photo as if on a sound record.
Technical Capacity and Competitive Analysis Home
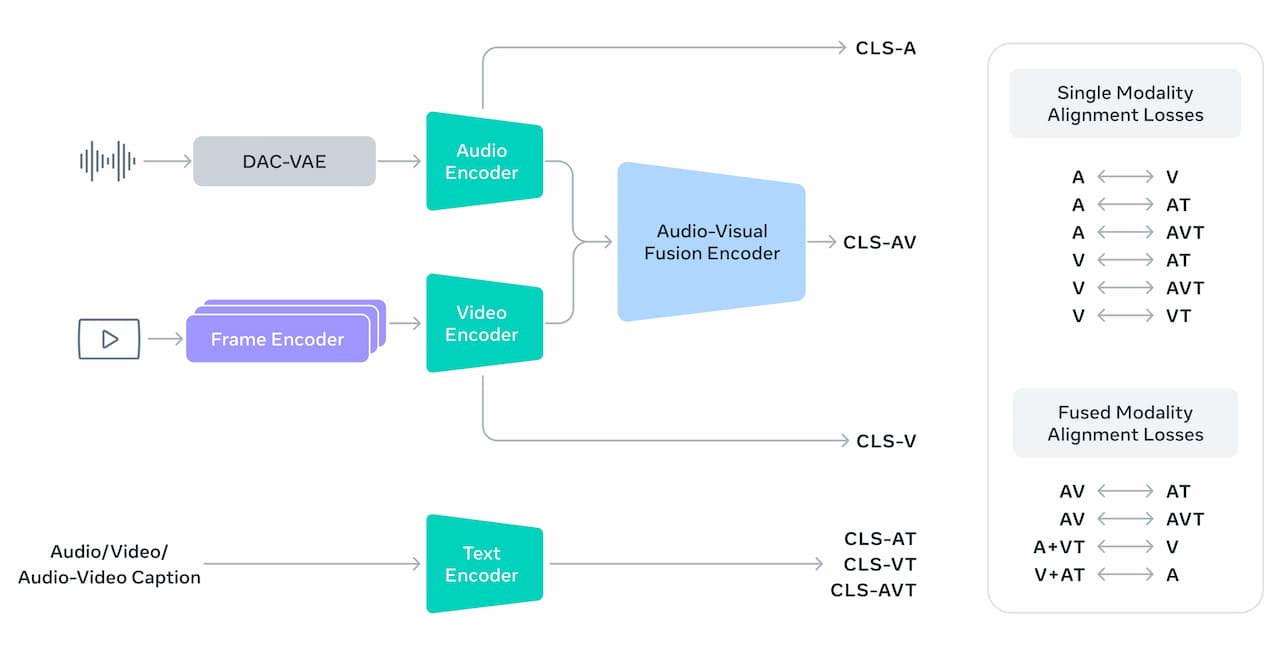
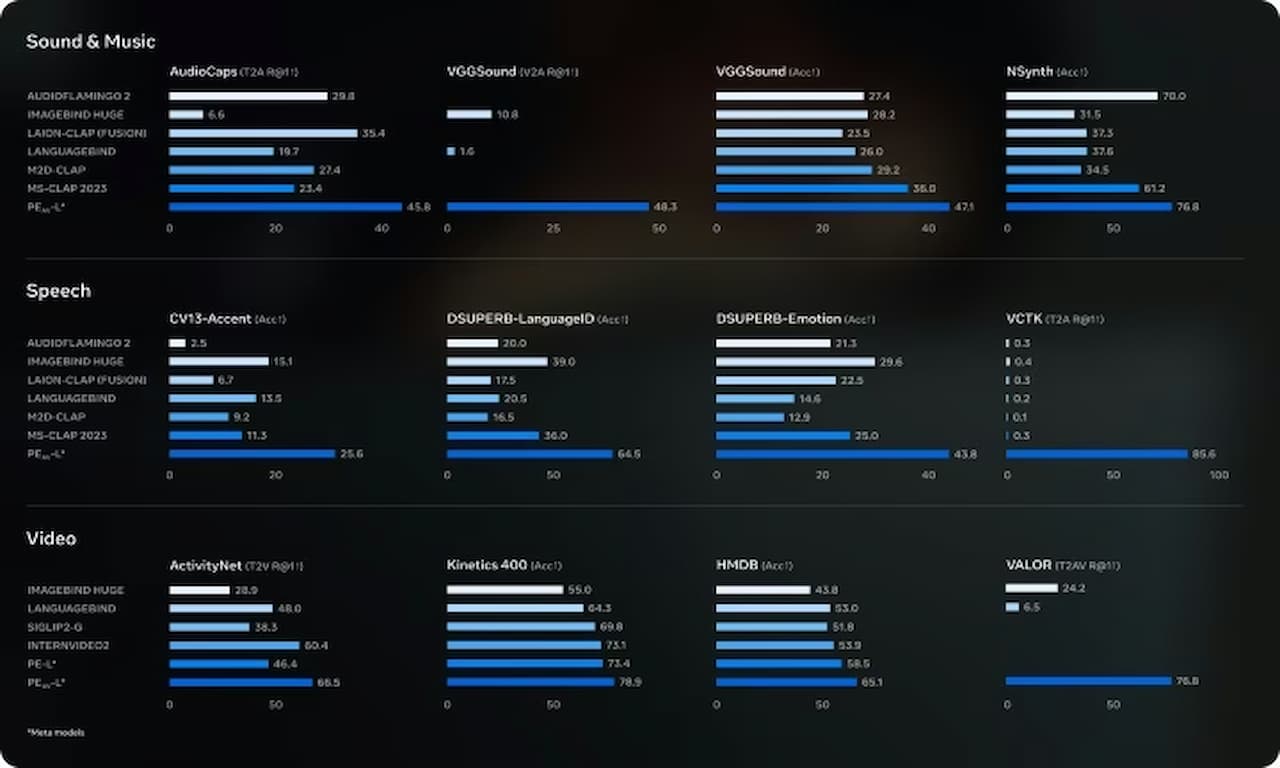
Behind SAM Audio’s success, Meta Transformer based architecture and training on a huge audio library. The sound for computers is normally composed of complex frequencies inside. But SAM Audio solves this mess with:
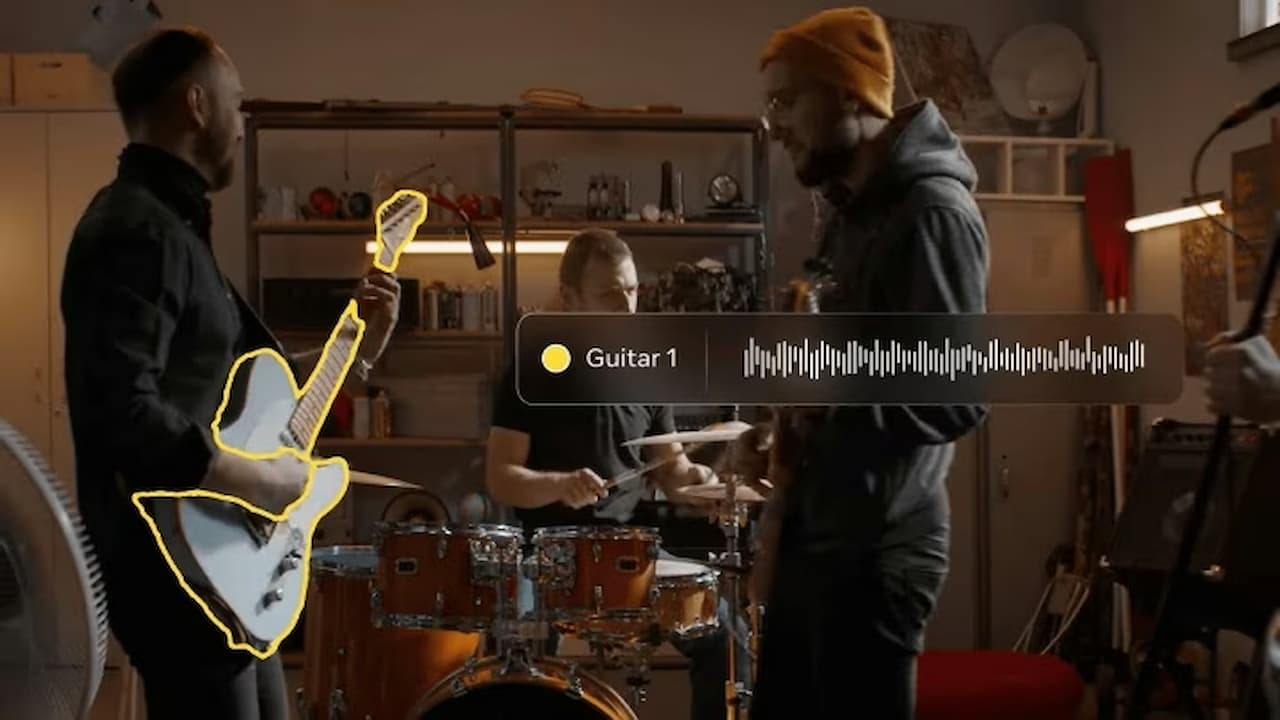
- Acoustic Signature Analysis: The model knows that each voice has a "fingerprint". They understand the tactical difference of the sound from the wire of a guitar with a keen wire and place them into separate layers.
- Zero Sample Learning: This term means that even a voice that the model has never been encountered before, it can be perceived as a "anger and a separate sound". For example, the voice of a newly-produced vacuum cleaner can separate the sound of television on the background even if not in the training set.
Current audio AIs (OpenAITags ElevenLabs etc.) usually "Text-to-Speech" is focused; i.e. takes a text and converts it to human voice. But SAM Audio, a "Ses Segmentation and Manipulation" model. This brings it to a "mimar" position, rather than a "producer" that can separate and re-manage the parts of the sound universe.
Objection of the voice
Models such as ElevenLabs produce the sound as a single whole. SAM Audio defines each element in a audio file (e.g. air conditioning noise in the background, the breath voice of the speaker and the echo on the room) as independent objects.
Difference: While other models are trying to print noise, SAM Audio noise "slow". This can remove only unwanted part with a surgical precision without damaging the original sound at all.
Naturality and Acoustic Awareness
Although OpenAI Voice models offer high naturality, they often give the best results in studio-like sterile environments. Technical superiority of SAM Audio, sound spatial acoustics Home understand.
Emo Toning: SAM Audio analyzes not only the frequency of the voice, emotional accents inside and pauses as "anlamsal". It has the processing capacity by distinguishing the sound from vibrations (micro-hythms) that a voice gets scared or cheer.
Low Delay Time and Efficiency
SAM Audio, Meta "Efficient Segmenter" Built on architecture. Instead of reading all the file while processing audio data, this architecture makes simultaneous operation by separating the voice into small "token".
Technical Advantage: While complex operations of other models (voice cloning or cleaning) take longer periods on cloud servers, SAM Audio works with much lower latency thanks to its optimized structure. This is her live posts and real-time translations for a step ahead of its competitors.
Zero-Shot Capacity & Flexibility
OpenAI and ElevenLabs models usually require intensive training on certain languages and audio tones. SAM Audio can instantly identify and isolate a voice (e.g. a very rare music tool) with its "Zero-shot" capacity. This proves that the model does not pill in predefined categories.
How to Use?
Meta, SAM Audio Since the model (as in the stage of discovery) has not yet been added to applications such as WhatsApp or Instagram for the last user. But there are two main ways to use this technology:
Meta AI Demo and Research Pages
Meta, new models are often Meta AI Research The website offers interactive demos.
- Step 1: Go to the official "Segment Anything" website of Meta AI.
- Step 2: Upload a audio file in the demo section.
- Step 3: Click the region you want to separate on the Specogram (audio visual map) or type a script like "just leave the human voice" in the text box.
- Step 4: Listen and download the audio layers that the model does not separate.
For Developers and Technical Users
SAM Audio is a basic model with open source code. If you have knowledge of Python at the basic level, or if you are a programmer:
- Code Access: Meta GitHub You can download the weights and codes of the model from the page to your computer.
- Hugging Face: These models are optimized by the community Hugging Face You can test directly on the browser.
- API Usage: To improve your own applications, you can add the library of the model to your project.
Uses and Daily Life Effects
SAM Audio is a practical and powerful tool beyond a theoretical success with the ability to separate audio data into parts:
- Accessibility: Solves "Kokteyl Party Problem" in hearing aids. In noisy environments such as cafe or restaurant; singular objects such as fork-byek and whirltu make the sound of the target speaker only.
- Production: Minimizes shooting errors in cinema and content production. An ambulance sir or wind sound that goes back without disturbing the dialogue in the external shots can be removed from the record "like pulled with tweezer". Müzisyens can separate old records in seconds to vocal and instruments.
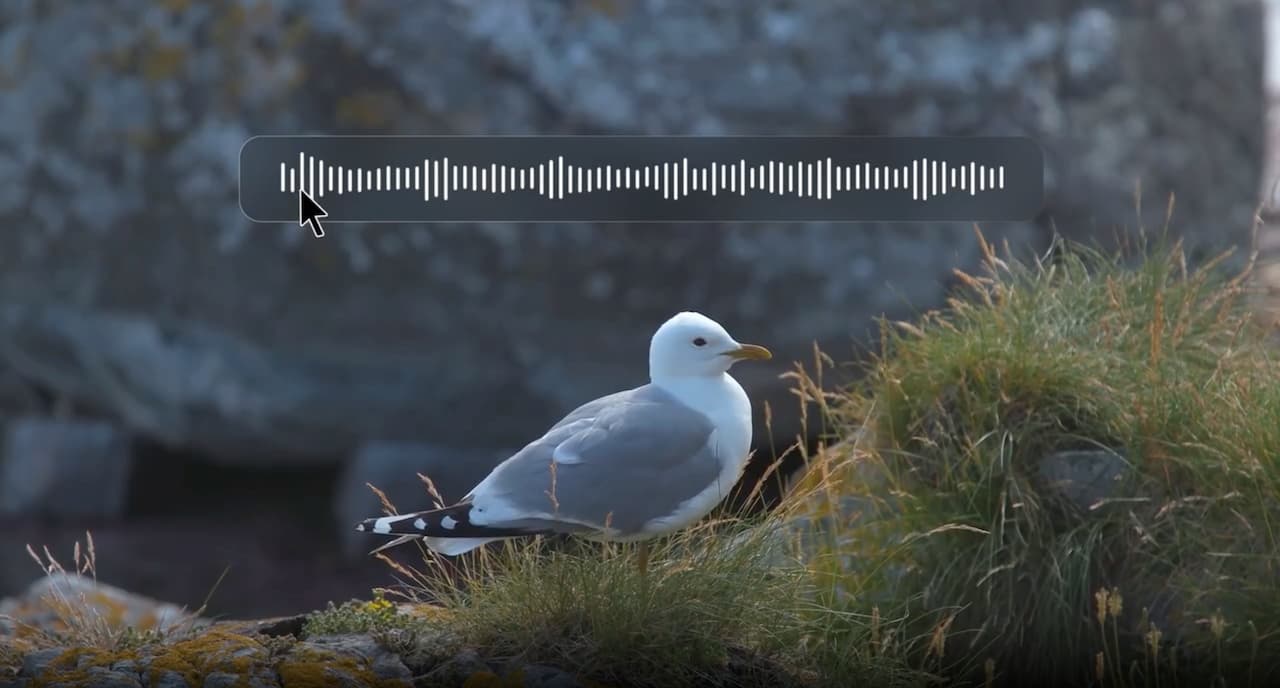
- Security & Science: Instantly detects specific sounds such as glass fracture or scream in city safety. In nature sciences, it facilitates ecological tracking by isolated the sound of a single living type through a complex forest record.
The perfect manipulation of sounds from this, digital counterfeiting (deep) and the risk of privacy violations. But Meta is positioning this model as a more creativity and accessible technology.
This model in the near future smartphone operating systems integrated. This will mean instant editing of the environmental noise in phone calls without the need for professional software of audio layers in captured videos.
How To Use In The Near Future?
When technology has become the latest, it will enter our lives in this way without requiring a special technical knowledge:
Meta SAM Audio technology converts sound to digital objects that can be controlled from a simple data. Smart phones Unlike standard noise blocking, the sound makes a surgical intervention by objecting. In a phone call, baby crying on the back or street noise is completely separated from the speaker; external sounds are destroyed by studio precision and only a clear voice is transmitted to the opposite side.
Social media and video editing The model gives the user a "visual eraser" by separating the audio channel into pieces like a jigsaw. In the video loading phase, unwanted sounds from automatic defined sounds such as wind, birds or traffic can be deleted by one click. SAM Audio allows you to produce professional quality content by filling the deleted audio cavity with a natural silence.
Hearing Aids in the field, "Kokteyl Party Problem". Thanks to the "Solving Mode" users can code and jealousy as "unwanted object" on the side table. This technology improves social interaction from the root, allowing the device to transmit only the targeted sounds in the crystal clear.
AdminHIX AI: Çok Yönlü İçerik Üretim Platformu Rehberi
Stream Ring: Yapay Zeka ile Güçlendirilmiş Akıllı Yüzük Satışa Açıldı!