Large Language Models (LLM) When discussing the reliability of operating systems, it is usually focused on the number of parameters or training data of the model. But most often there is a very basic technical detail that overlooks: what format we offer data to the model? LLM data format comparison is a critical element that not only responds to "smart" of an artificial intelligence system, but also directly determines operational costs.
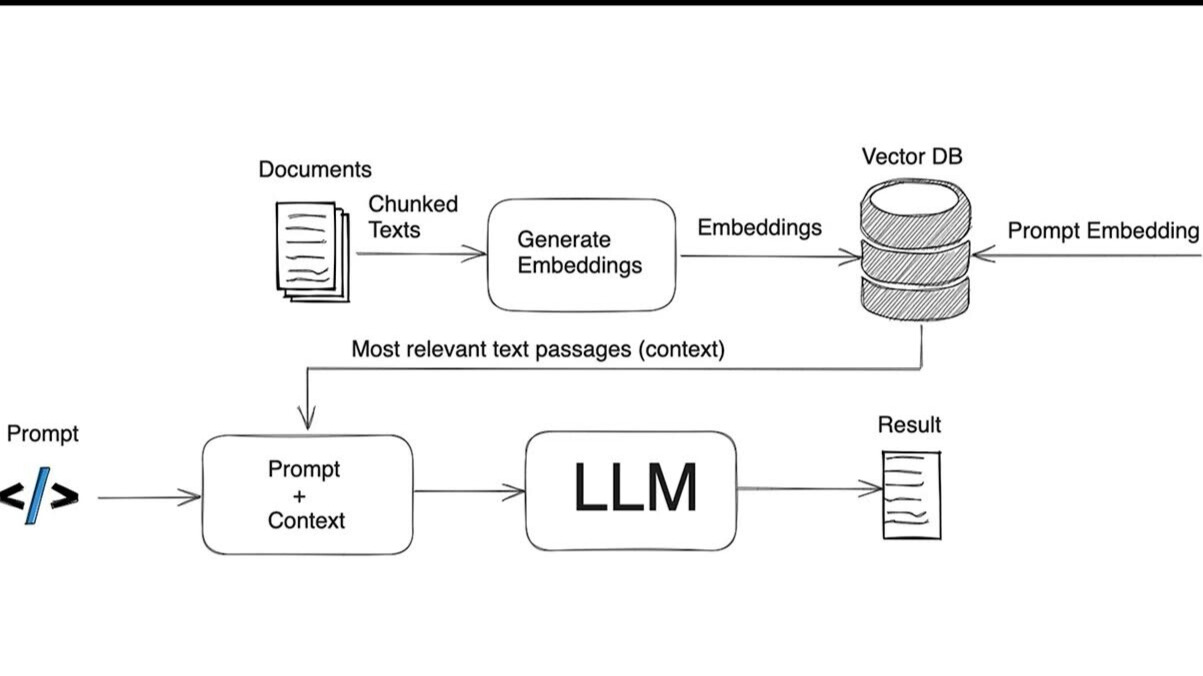
Especially in RAG pipeline optimization processes, tables or hierarchical data (JSON, CSV, Markdown etc. ) The method of transferring to the model affects the overall success of the system. The choice of wrong format can reduce the proportion of artificial intelligence data accuracy as a result of incorrect interpretation of the model or superfluous high LLM token cost with your budget. In this deep review, we analyze the performance of different data formats with technical data and benchmark results.
What Format Prefers to Mean LLMs Tables?
1.000 different questions on artificial intelligence models via 1,000 registered data sets controlled experimentsreveals the effect of format selection on system accuracy dramatically.
- Markdown-KV (Key-Value) Format: In the tests conducted, 60.7% of accuracy were peaked. Key to each record rather than classic tables: this structure that offers value pairs makes it easier for the model to establish the relationship between data.
- XML and INI: It follows Markdown-KV with accuracy rates around 56%. But the cost of the XML is quite high.
- CSV and JSONL Performance: Surprisingly, the most used CSV JSONL performance in data science remained quite low. CSV 44.3%, JSONL stay at 45% accuracy. This indicates that LLMs are forced to sense raw data separated by comma.
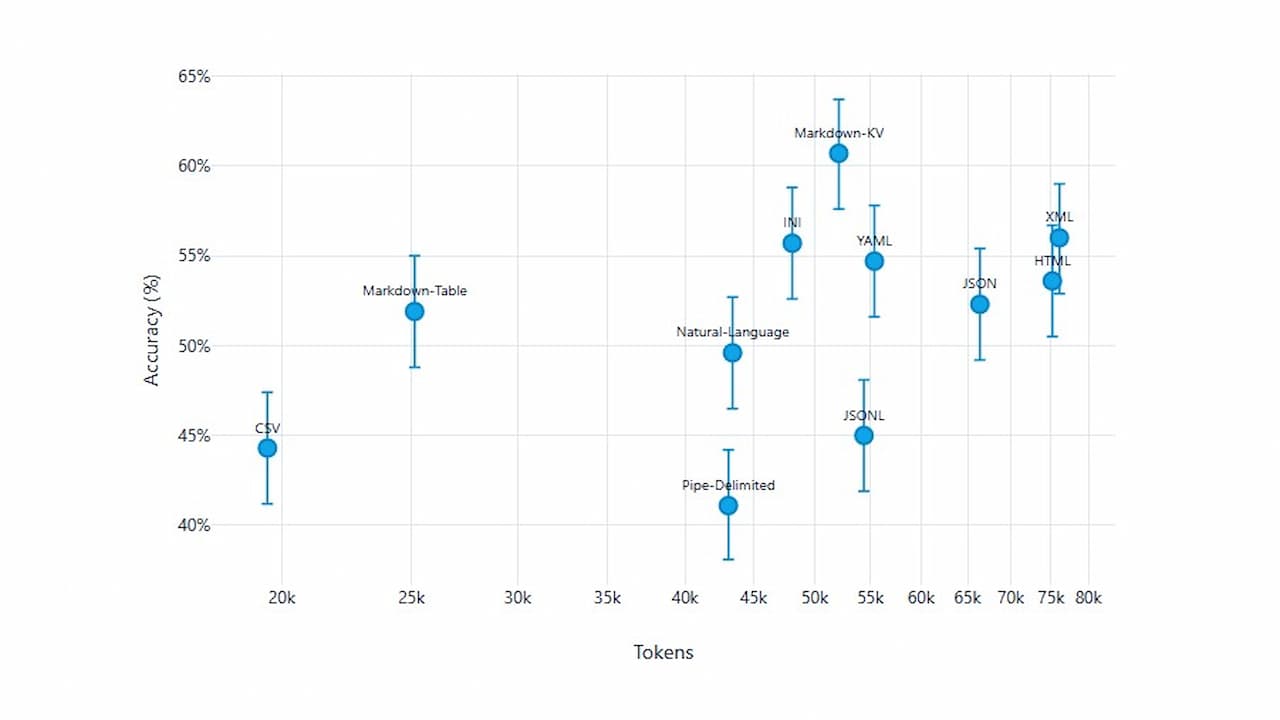
Token Efficiency: CSV, format consuming at least tokens (19,524 tokens) Although it has one of the lowest accuracy rates. Markdown-KV provides a 16-point accuracy advantage, although it consumes 2.7 times more tokens than CSV.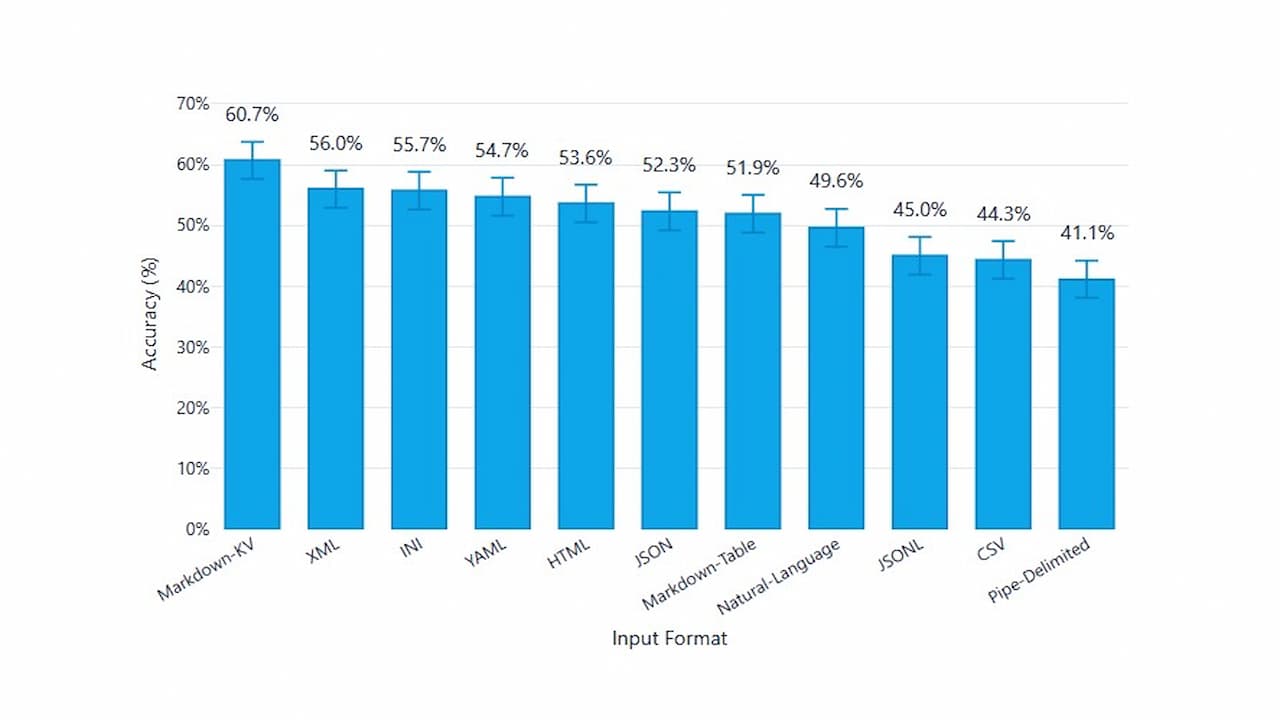
What is the Best Format in Havarchy (Internal) Data?
Modern AI systems are generally required to process internal data such as API responses or configuration files. LLM data format comparison offers varying results from model to model.
- YAML- Accuracy Leader: GPT-5 Nano and Gemini 2.5 Flash Lite models Home showed the highest performance. The visual hierarchy based on the entrance provides the complex structures of the model "see".
- Markdown- Cost Champion: Markdown has been the most token-efficient format in all models. 34-38% from JSON consumes about 10% less tokens from YAML. Ideal for those who want to minimize the cost while maintaining the required accuracy.
- JSON's Poorness: Despite the widespread use JSONshowed worse performance than expected in GPT-5 and Gemini models. JSON has given acceptable results since format precision is low in Llama 3.2 3B Instruct model.
- How Much From XML: XML has both the highest token consumption and its accuracy rates are generally included in the last row. Repeated label structures () can distribute the attention mechanism of the model (attention).
How Does Format Selection Affect RAG Pipeline Accuracy?
- What Is Affected? The accuracy of a RAG (Retrieval-Augmented Generation) system depends on how to feed the received information to the model. The wrong format leads the model to wrong reporting, based on "halflation".
- Why Important? A 10% reduction in artificial intelligence data accuracy rate may mean disaster for customer service bot or financial analysis tool.
How to Optimize? If the accuracy is important above all, Markdown-KV or YAML should be used. If the budget is restricted and the data is dense, Markdown tables are a good medium way.Where to Use? This optimization is vital at any point where the database query results are transferred to LLM.Who Do? Data engineers and AI architects must convert the format of data in prompt engineering phase into a standard.Token Cost and Performance Balance
Token consumption of data formats is direct operating cost. For example, XML format requires 80% more tokens than Markdown. This means you pay almost two times money to process the same data.
Performance-Material Matrix:
- Accuracy Priority (High Budget): Markdown-KV (for Sheets), YAML (for Nested data).
- Balance Priority: Markdown Tables.
- Low Cost Priority (Low Accuracy Acceptance): CSV or JSONL.
Strategic Recommendations for Application
According to the results of LLM data format comparison, using CSV or JSON can restrict the potential of your system. It is recommended to follow these steps while maintaining technical depth:
- If the table data is used intensively in your system, add an intermediate layer that converts the data to Markdown-KV format before sending it to the model.
- Standardize YAML format for complex configuration files or catalogs.
- Your Model (GPT, Llama, Ship etc. ) Make small-scale benchmark tests with your own data set to determine which format is more responsive.
- Download XML usage minimum to prevent unnecessary token waste.
Home "right" there is no format; but according to your goals "optimize" format. If the accuracy is critical, YAML and Markdown-KV are the strongest standards of the world of AI for 2025 and later, if the cost is critical. The success of the system depends not only on the presence of the data, but the model consumes it in the most pure and understandable form.
Large Language Models (LLM) When discussing the reliability of operating systems, it is usually focused on the number of parameters or training data of the model. But most often there is a very basic technical detail that overlooks: what format we offer data to the model? LLM data format comparison is a critical element that not only responds to "smart" of an artificial intelligence system, but also directly determines operational costs. Especially in RAG pipeline optimization processes, tables or hierarchical data (JSON, CSV, Markdown etc. ) The method of transferring to the model affects the overall success of the system. The choice of wrong format can reduce the proportion of artificial intelligence data accuracy as a result of incorrect interpretation of the model or superfluous high LLM token cost with your budget. In this deep review, we analyze the performance of different data formats with technical data and benchmark results. What Format Prefers to Mean LLMs Tables? 1.000 different questions on artificial intelligence models via 1,000 registered data sets controlled experiments reveals the effect of format selection on system accuracy dramatically. Markdown-KV (Key-Value) Format: In the tests conducted, 60.7% of accuracy were peaked. Key to each record rather than classic tables: this structure that offers value pairs makes it easier for the model to establish the relationship between data. XML and INI: It follows Markdown-KV with accuracy rates around 56%. But the cost of the XML is quite high. CSV and JSONL Performance: Surprisingly, the most used CSV JSONL performance in data science remained quite low. CSV 44.3%, JSONL stay at 45% accuracy. This indicates that LLMs are forced to sense raw data separated by comma. Token Efficiency: CSV, format consuming at least tokens (19,524 tokens) Although it has one of the lowest accuracy rates. Markdown-KV provides a 16-point accuracy advantage, although it consumes 2.7 times more tokens than CSV. What is the Best Format in Havarchy (Internal) Data? Modern AI systems are generally required to process internal data such as API responses or configuration files. LLM data format comparison offers varying results from model to model. YAML- Accuracy Leader: GPT-5 Nano and Gemini 2.5 Flash Lite models Home showed the highest performance. The visual hierarchy based on the entrance provides the complex structures of the model "see". Markdown- Cost Champion: Markdown has been the most token-efficient format in all models. 34-38% from JSON consumes about 10% less tokens from YAML. Ideal for those who want to minimize the cost while maintaining the required accuracy. JSON's Poorness: Despite the widespread use JSON showed worse performance than expected in GPT-5 and Gemini models. JSON has given acceptable results since format precision is low in Llama 3.2 3B Instruct model. How Much From XML: XML has both the highest token consumption and its accuracy rates are generally included in the last row. Repeated label structures ( ) can distribute the attention mechanism of the model (attention). How Does Format Selection Affect RAG Pipeline Accuracy? What Is Affected? The accuracy of a RAG (Retrieval-Augmented Generation) system depends on how to feed the received information to the model. The wrong format leads the model to wrong reporting, based on "halflation". Why Important? A 10% reduction in artificial intelligence data accuracy rate may mean disaster for customer service bot or financial analysis tool. How to Optimize? If the accuracy is important above all, Markdown-KV or YAML should be used. If the budget is restricted and the data is dense, Markdown tables are a good medium way. Where to Use? This optimization is vital at any point where the database query results are transferred to LLM. Who Do? Data engineers and AI architects must convert the format of data in prompt engineering phase into a standard. Token Cost and Performance Balance Token consumption of data formats is direct operating cost. For example, XML format requires 80% more tokens than Markdown. This means you pay almost two times money to process the same data. Performance-Material Matrix: Accuracy Priority (High Budget): Markdown-KV (for Sheets), YAML (for Nested data). Balance Priority: Markdown Tables. Low Cost Priority (Low Accuracy Acceptance): CSV or JSONL. Strategic Recommendations for Application According to the results of LLM data format comparison, using CSV or JSON can restrict the potential of your system. It is recommended to follow these steps while maintaining technical depth: If the table data is used intensively in your system, add an intermediate layer that converts the data to Markdown-KV format before sending it to the model. Standardize YAML format for complex configuration files or catalogs. Your Model (GPT, Llama, Ship etc. ) Make small-scale benchmark tests with your own data set to determine which format is more responsive. Download XML usage minimum to prevent unnecessary





 Admin