Turkish Artificial Intelligence Models: BİLGE, Kumru, T3 AI and Others
Automatically translated
 Writer
The large language models have a very basic fact that they are reviewing while crocheting the world: No matter how talented giant models with silicone valley outlets, the work becomes different when it comes to English. Most of us have noticed the strange translation cochan phrases that are put together when working with these models, meaningless of idioms, or simply extending a simple technical problem to unnecessary place. Here, at this point, domestic artificial intelligence projects have become a technical obligation, not only being a national pride.
Today, the artificial intelligence ecosystem developed in Turkey is not a simple interface in front of OpenAI or Anthropic models. A strong infrastructure is built with the contribution of open-source communities trained with its own weights and focused directly on the state-of-the-art structure of Turkish.
How to Denersin?
A brief table first: how you can access this model today and whether the model is switched on (14.10.2026).
Home | Developer | How to access? | Outdoor / Indoor |
|---|---|---|---|
News | TUBITAK | Not yet open to general use; for pilot projects © Copyright 2018. All Rights Reserved. via TUBITAK TICKET | Close |
Home u | VNGRS | Home demosu; Kumru-2B on Hugging Face | 7,4B off, 2B open (Apache 2.0) |
T3 AI | T3 Foundation and Baykar | Opened as beta at TEKNOFEST Social Platform in 11.07.2025 | Open source target; not shared the downloadable weight |
Trendyol LLM | Home | Hugging FaceDownloadable | Outdoor weight |
Home | Bosphorus University TABILab |
Hugging FaceDownloadable
Open, non-commercial academic use alone m
Home
Home
Private to institutions, platform built into institution
Close
Why Global Models Are Not Yet?
While global AIs are trained with trilyons, a little part of this data consists of Turkish. This situation brings two major issues:
Token Waste and High Billing:
token systems designed according to English cannot solve the root and additional logic of Turkish. A simple word divides 3-4 pieces (token). This adds both API usage bills and extends the system’s response generation time in bar.
Cultural and Legal Context:
It is quite risky to take a contract analysis suitable to the Turkish Commercial Code of a global model or to classify the customer’s complaint with the right feeling. Because the model references Western culture and American law logic as default.
In order to close this deficit, the academy focused on developing Turkish artificial intelligence models by combining public and independent initiatives in Turkey.
What It Works On The Site? Featured Native Models
Artificial intelligence projects in Turkey Home; responds to different needs from state-supported large-scale infrastructures to agile solutions.
1. BİLGE: Extensive Language Model Family from TÜBİTAK
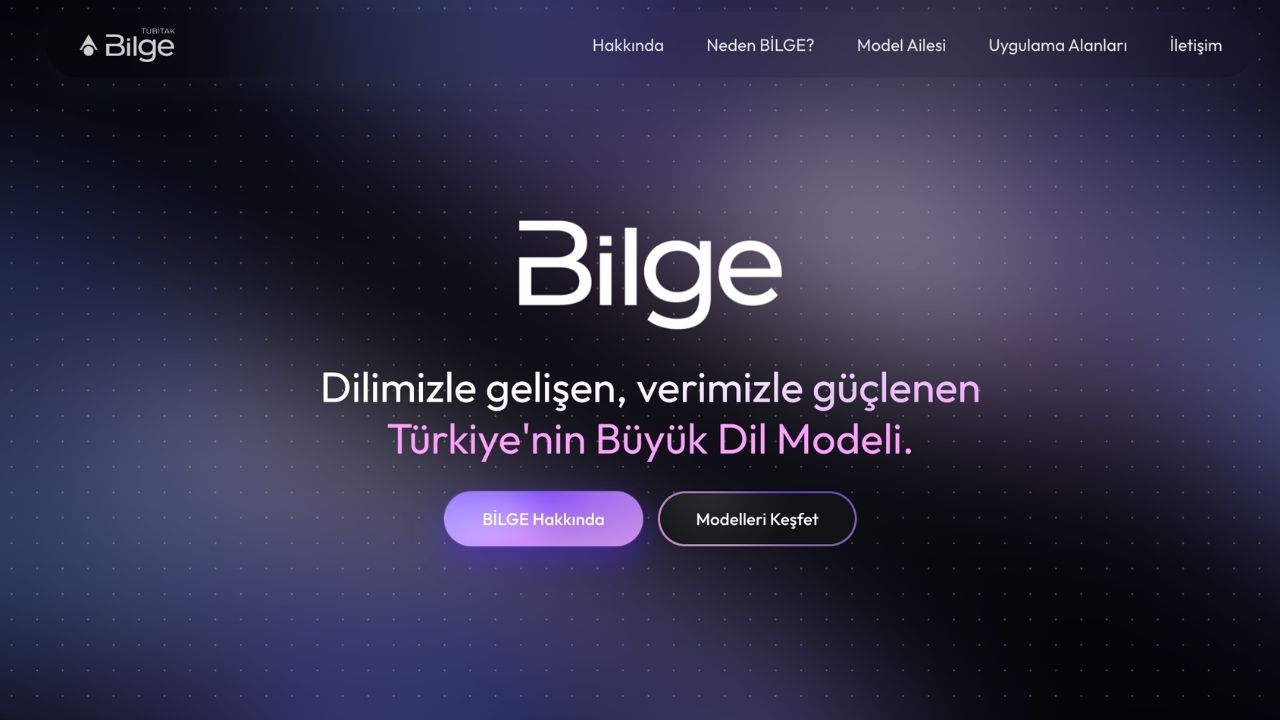
The most concrete and comprehensive step on the public side is implemented by TÜBİTAK BİLGEM News The project was. The biggest claim of BİLGE is to use Turkish as a native language without translating from another language.
Different Sizes For Different Needs:
BİLGE is not a single model, a family. With 1B designed for mobile and end devices, the performance and efficiency balance were trained from 9B to scratch. BİLGE 27B has been developed with Continuous Pre-Training method with Turkish data. Designed for complex reasoning tasks, BİLGE 122B is still in the development phase.
Devasa English Korpus:
The training started with about 1 trillion vocabulary raw Turkish data pool. 250 billion high quality tokens were selected from this pool and the data was enriched with 500 billion synthetic data. The aim is to grasp the model’s idioms, appliques and technical terms in Turkish context.
Low Energy & Cost:
It is aimed to spend less processing power because it uses a token that is appropriate to Turkish. Public institutions are designed for corporate applications where data security is critical.
Access status: As of 14.10.2026, BİLGE is not open to general use. For pilot projects according to the official site, TUBITAK TICKET can be contacted. Access-related announcements were announced only to be made from the official channels of TÜBİTAK with the Ministry of Industry and Technology.
2. 2. Kumru AI: Fast, Focused and Lightweight
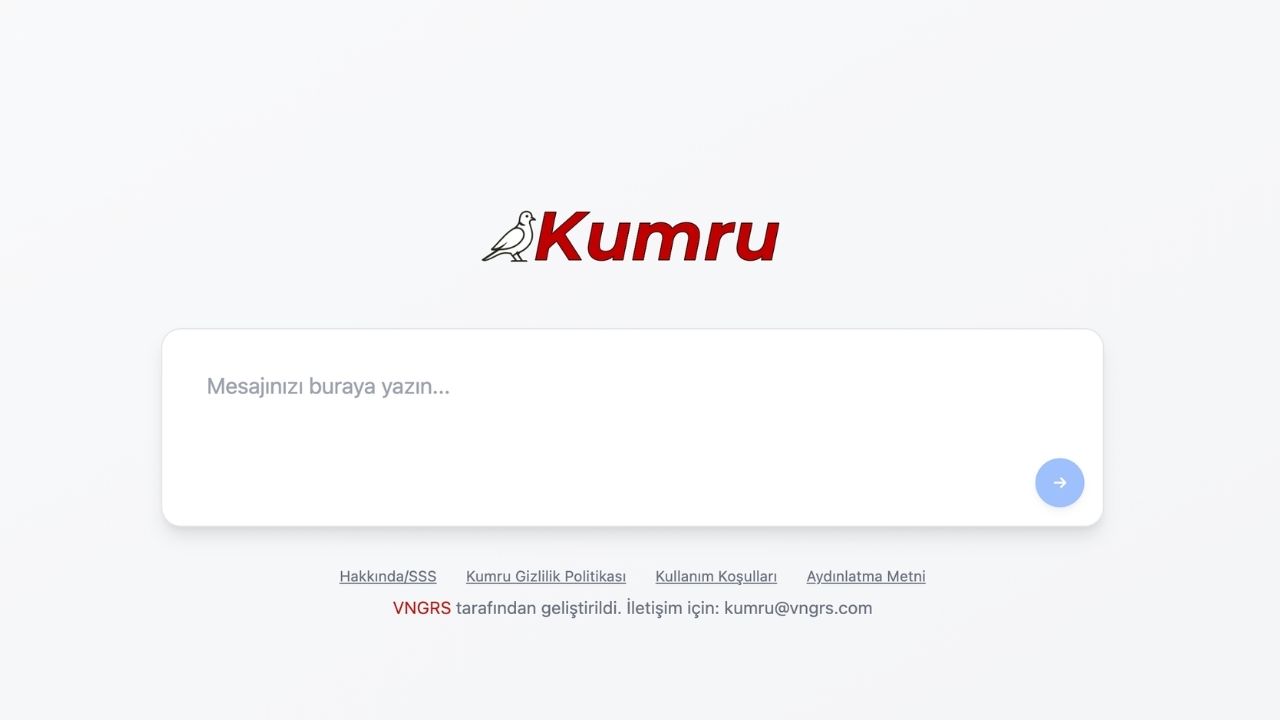
In the world of venture, models focus on functionality rather than entering the huge parameter race. From Kumru AI, A Turkish LLM alternative that businesses can run on their servers without spending huge budgets.
Text abstracting, categorizing customer demands and establishing natural Turkish dialogue Very successful modelprovides high speed of distractions without removing hardware resources.
VNGRS trains from scratch for Turkish Kumru 7,4 billion parameters and can work on a GPU with 16 GB VRAM. Home You can try the demo on it; 2 billion parameters Kumru-2B is open with Apache 2.0 license on Hugging Face. For technical details and limits Kumru AI guide News See.
3. T3 AI: Open Source and Community Power
T3 AI developed in Baykar business association with Turkish Technology Team Foundation (T3 Foundation) represents the community size of the work. In Model 11.07.2025, TEKNOFEST has been opened to use with beta version in the Social Platform. During the announcement, it was announced to contribute to the project of 1,792 volunteers from 67 provinces.
The project says it was developed as open source; but the number of parameters and model weights were not yet shared where to be downloaded. If the weights are opened, it can be easy to train special models in areas such as law or medicine.
4. Academic Spine and Outdoor Weight Initiatives
The ecosystem in Turkey is not only limited to three names:
Trendyol LLM:
The first version of Trendyol LLM (2024) was trained with 10 billion tokens on the LLaMA 2 7B model of Meta. Next versions passed Qwen 2.5 7B, Qwen 3 8B and Gemma 3 12B bases. Trendyol-LLM-Asure-12B shared in February 2026 can also work and set for e-commerce tasks, such as abstracting, question-cevap. Models are mainly shared on Hugging Face.
TOURNA:
TURNA, developed by TABILab in Boğaziçi University Computer Engineering Department, is a 1,1 billion parameter encoder based on UL2 frame, a Turkish language model. Designed for both understanding and text generation tasks and shared for non-commercial academic research on Hugging Face.
Zemberek Heritage:
Open source English natural language processing library HomeOne of the tools that have been applied for many years in basic works such as root-ex solutioning.
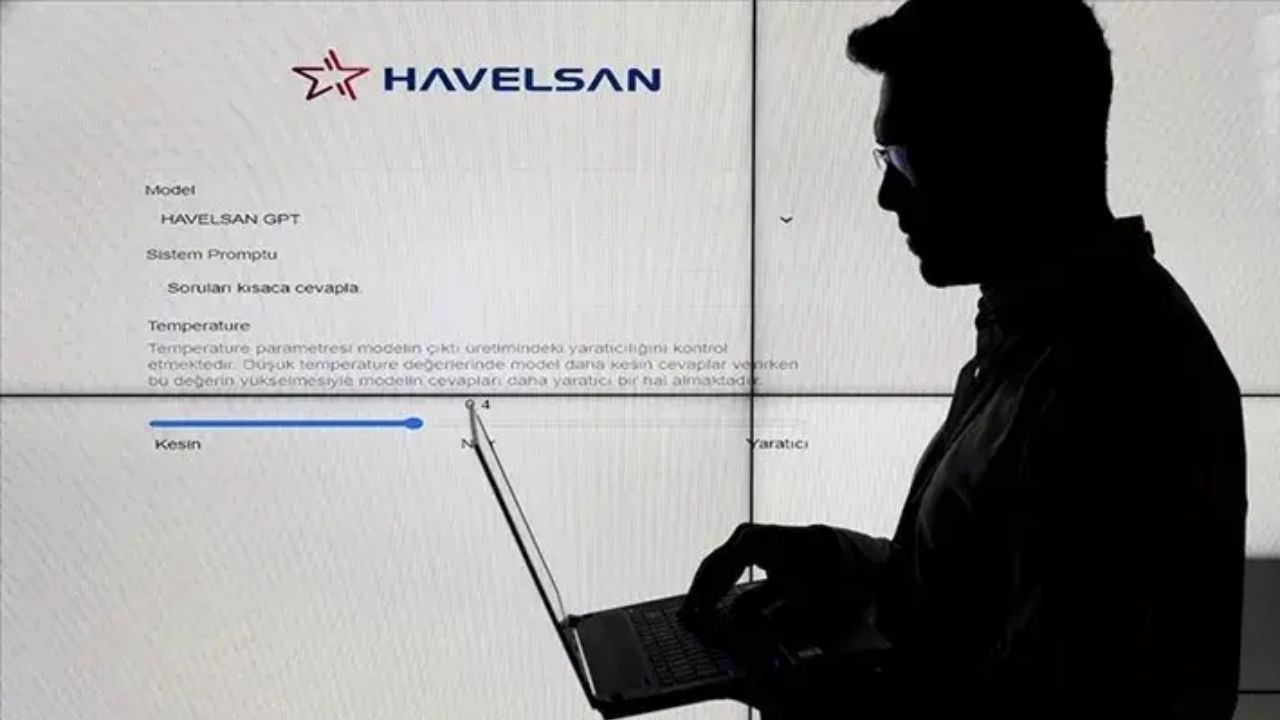
5. MAIN GPT (HAVELSAN): Native Brain of Defense and Corporate Safety
One of the most critical feet of domestic AI moves is thrown on the defense industry and public security side. Developed to protect in-house data security and high privacy standards by HAVELSAN HAVELSAN MAIN GPT It stands out as one of the corporate AI infrastructures that can work off Turkey.
The root (Multi Artificial Intelligence Network) promoted in 01.02.2024 of HAVELSAN, is a platform where institutions can establish artificial intelligence assistant based on their data. The closed circuit is designed to work; the purpose does not leave the data outside the institution. At the first stage, text-based works; content abstracting is able to process information from open source data and code writing.
6. Aigency: Early Term Turkish Language Model Initiative Home
Şanlıurfa-based eCloud Software Technologies started developing in 2022 Aigencyintroduces itself as one of the first domestic language models in Turkey. According to the news on the local press, Meta’s LLaMA is based on 3 models and focuses on Turkish text production, content analysis and corporate communication processes. An independent assessment of the model has not yet been published.
Overview of models:
Home | Developer | Scale / Approach | Basic Focus | Largest Plus |
|---|---|---|---|---|
News | TUBITAK | 1B, 9B, 27B (122B is developed) | Public, Corporate, Digital Domination | 1 trilyon word raw data pool, domestic altyap |
Kumru AI | VNGRS | 7,4B from scratch training; 2B open | In-house (B2B) document processing, summarize |
Low server cost, quick response time
T3 AI
T3 Foundation and Baykar
Parameter count not disclosed
Community Based Turkish LLM
Volunteer data set, open source ecosystem target
Trendyol LLM
Trendyol Tech
7B - 12B outdoor weight
E-Commerce and Customer Dialogue
Directly integrated into practical scenarios
HOME GPT
Home
Corporate & Isolated Language Model
Defense, Public and Corporate Data Security
Closed circuit (on-premise) operation
Aigency
eCloud Software
Early Stage Language Architecture
Text Production and Corporate Communication
Early term initiative focusing on Turkish text production
Why Important for Developers and Companies?
Choosing a native language model is not only the idea of "we support the ground technology"; directly hosting the advantages of companies interested in their pocket and legal processes:
KVKK and Data Security:
A serious headache due to the regulation of a bank, hospital or e-commerce site to receive user data and send it to an API abroad. Local models do not exit the data from the institution because they can work directly on their server (on-premise).
Less Hardware, More Speed:
Instead of hundreds of billion parameters bulk models, you can easily run on a single middle segment GPU, a 7B or 14B compact model trained for a specific job. That’s why server and electricity costs are seriously down.
Break Out Dependency:
Global artificial intelligence companies can double API prices at a night or bring access restriction to your business to stop. Outdoor weights Hugging Face native models that you can download from platforms like, allow you to keep your software architecture completely in your own control.
With the opening of national supercomputer resources such as TRUBA and carrying out software experience acquired in the defense industry (ASELSAN, HAVELSAN), artificial intelligence production in Turkey is rapidly spreading to the base. Now the matter is not only to print text; to create autonomous systems that really understand our native culture and language. Native models are also fully pushing the spine of this independence.
Writing the Future With Our Own Code
Artificial intelligence race is now measured not only with who has a larger server farm, but how realistic it touches the local needs of this technology. The models developed in Turkey; instead of copying the ready-made molds, it is placed in a line that presses many more feet, focusing on solving the subtleties of the Turkish, providing data security and reducing operational costs of companies. This point, from the corporate power of TICGE, Kumru AI and T3 AI, shows that an independent technology infrastructure that thinks and produces in its own language is no longer a appeal, but a tangible reality. To build the future with our own codes instead of consuming with others’ algorithms, the most critical step we can jump in digital age.
Some of the companies behind these models Turkish AI companies that stand out in 2026 Home We got in the article. For the technical details of Kumru Kumru AI guide look at people working on Turkish language models Masqot communities you can meet.
WriterDario Amodei'den Yapay Zeka Uyarısı: Sektör Yalan Söyledi
Gemini Ücretli mi? Ücretsiz Sürüm ve Tüm Planlar (2026)