



DeepSeek V4 Introduced: 1 Million Tokens and 1.6T Parameter!
Automatically translated
China Based DeepSeekWith V4 model, 1 million token contexts and 1.6 trillion parameters redefined scale, efficiency and cost balance in artificial intelligence.
What is DeepSeek V4 and Why Important?
The competition in the field of artificial intelligence is not only through the model accuracy; while the context length is redefined through parameters such as processing cost and scalability, the DeepSeek V4 model is positioned as one of the most concrete examples of this conversion. The question “What is DeepSeek V4?” refers not only limited to a new model definition, but also the fracture of large language models (LLM) technical architecture. The model’s 1 million token context capacity, long text processing, code analysis and a radical expansion in multi-stage reasoning tasks, 1.6 trillion parameter scale represents the new threshold that artificial intelligence reaches in calculation power.
This development is possible to handle more information in a single session in finance, law, software engineering and academic research especially in data intensive industries. Analysis processes that are attached to the context limit in traditional models can now be carried out continuously on much wider data clusters. This means not only performance rise, but also redesigning workflows.
DeepSeek V4 series means not only scale growth but also architectural redesign. The model family developed by DeepSeek is presented with two different structures including DeepSeek-V4-Pro and DeepSeek-V4-Flash. Open source on official Hugging Face collection The model released as 1M context standard aims to make the industry a new norm.
1 Million Token Artificial Intelligence: Grant Limits
One of the most remarkable innovations of DeepSeek V4, the 1 million token context capacity is evaluated as one of the biggest technical leaps ever in artificial intelligence models. While the token is defined as one of the smallest units that can be processed from a text, it means that the capacity reaches 1 million; hundreds of page documents can be analyzed at one time of large code bases or multilayer data sets.
This development creates a serious advantage especially in tasks requiring long context. For example; analysis of the entire text of a law, processes such as debugging in large-scale software projects, or extensive comparison of academic articles can now be performed in the whole way, not part parts. This greatly eliminates the problem of the model “light continuity”.
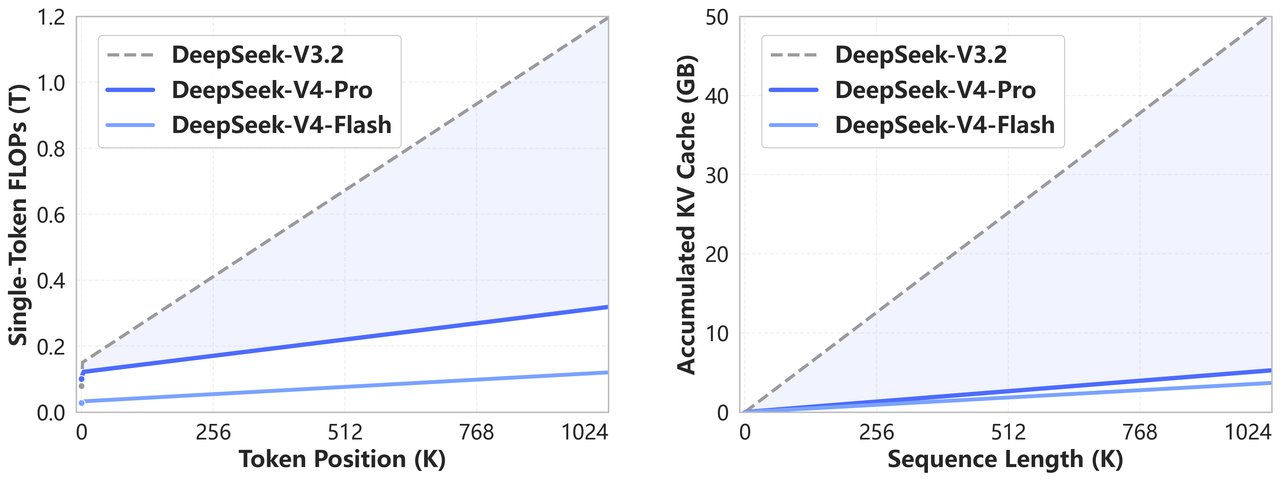
DeepSeek V4, Hybrid Attention architecture Thanks to its long context processing, it offers serious efficiency gains. The model with the combination of Compressed Sparse Attention (CSA) and Heavily Attention Compressed (HCA) can work with much lower calculation costs than previous generations. In particular, the use of KV cache in 1M token scenario is indicated to be significantly reduced.
Mixture of Experts Architecture: Scalable Intelligence Approach
The Mixture of Experts (MoE) architecture, located in the technical spine of DeepSeek V4, stands out as the basic mechanism, which enables the model to work efficiently despite the high number of parameters. This architecture allows the entire model to be activated only related “special” sub-networks for certain tasks instead of running at the same time.
This approach offers a serious calculation advantage compared to classic intensive models. Instead of using the entire model with 1.6 trillion parameters, only the necessary parts are activated; both reducing the cost of processing and optimizing the response time. This situation stands out especially as a critical factor that directly affects cost-performance balance in API usage.
MoE architecture also provides higher accuracy rates, allowing the model to be experts in different types of tasks. This makes DeepSeek V4 not only big but also a “smart scale” model.
Pro and Flash models in DeepSeek V4 architecture are divided into different active parameters levels. DeepSeek-V4-Pro 1.6T is working with 13B active parameter in total parameter of 49B, DeepSeek-V4-Flash 284B. This structure is the main advantage of MoE architecture “calculation as much as required” implements the principle directly.
The Manifold-Constrained Hyper-Connections (mHC) structure, located in the architecture of DeepSeek V4, enables the model to protect the expression power while stabilizes the flow of information between layers. In addition, the use of Muon optimized offers faster convergence and more stable learning dynamics in the educational process.
KV Cache Efficiency: Secret Strength of Long Connect
Another element that is critical to the practical use of long context capacity is the KV Cache (Key-Value Cache) optimization. KV Cache efficiency developed in DeepSeek V4 significantly reduces the operation load, allowing the model to use previous tokens without recalculation.
This technical improvement directly affects performance in applications that require long dialogues and continuous data flow. For example; an artificial intelligence system with long-term interaction with a user can produce fast and consistent responses without having to reprocess all history in each new entry.
KV Cache optimization also plays a critical role in terms of energy efficiency. Less calculation requirement means lower energy consumption; this situation directly affects operational costs in large-scale data centers.
DeepSeek V4-Pro is working with about 10% KV cache usage in 1M context scenario compared to DeepSeek-V3.2, while inference FLOPs side also offers a more efficient structure at 27% level. This optimization provides significant performance increase especially in long chat and agent-based applications.
DeepSeek V4 Pro Features: Performance in Corporate Level
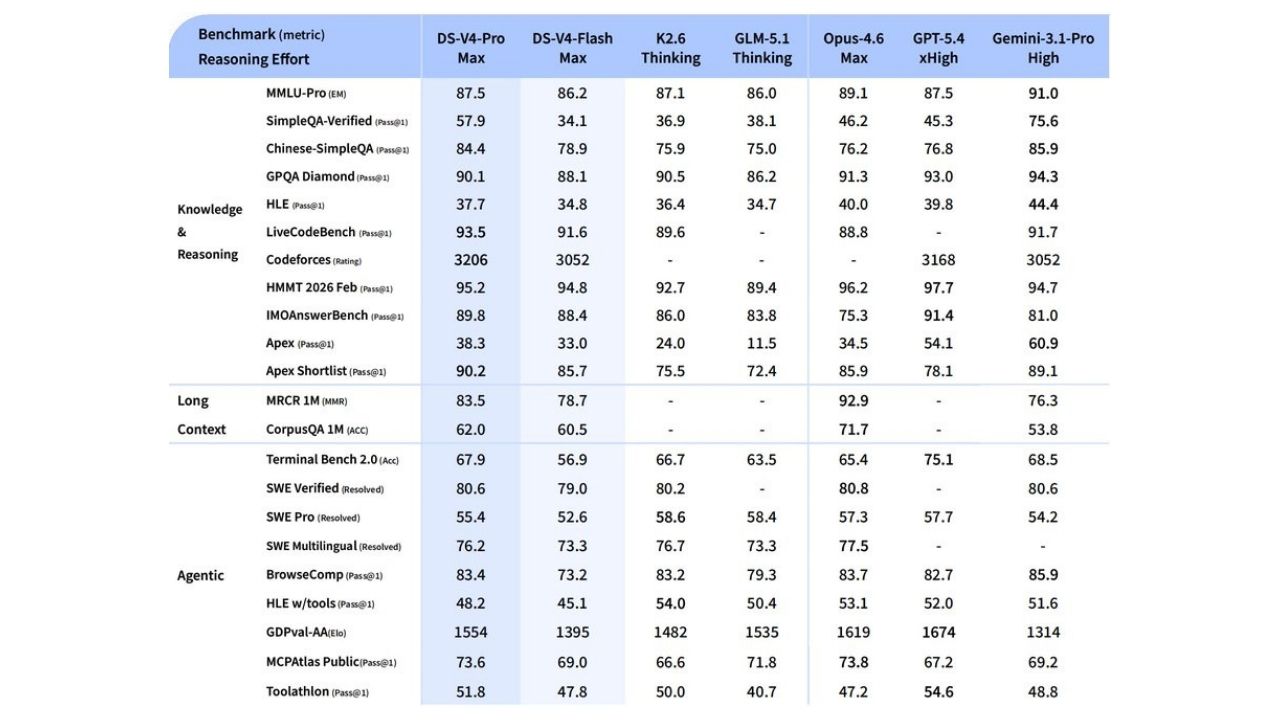
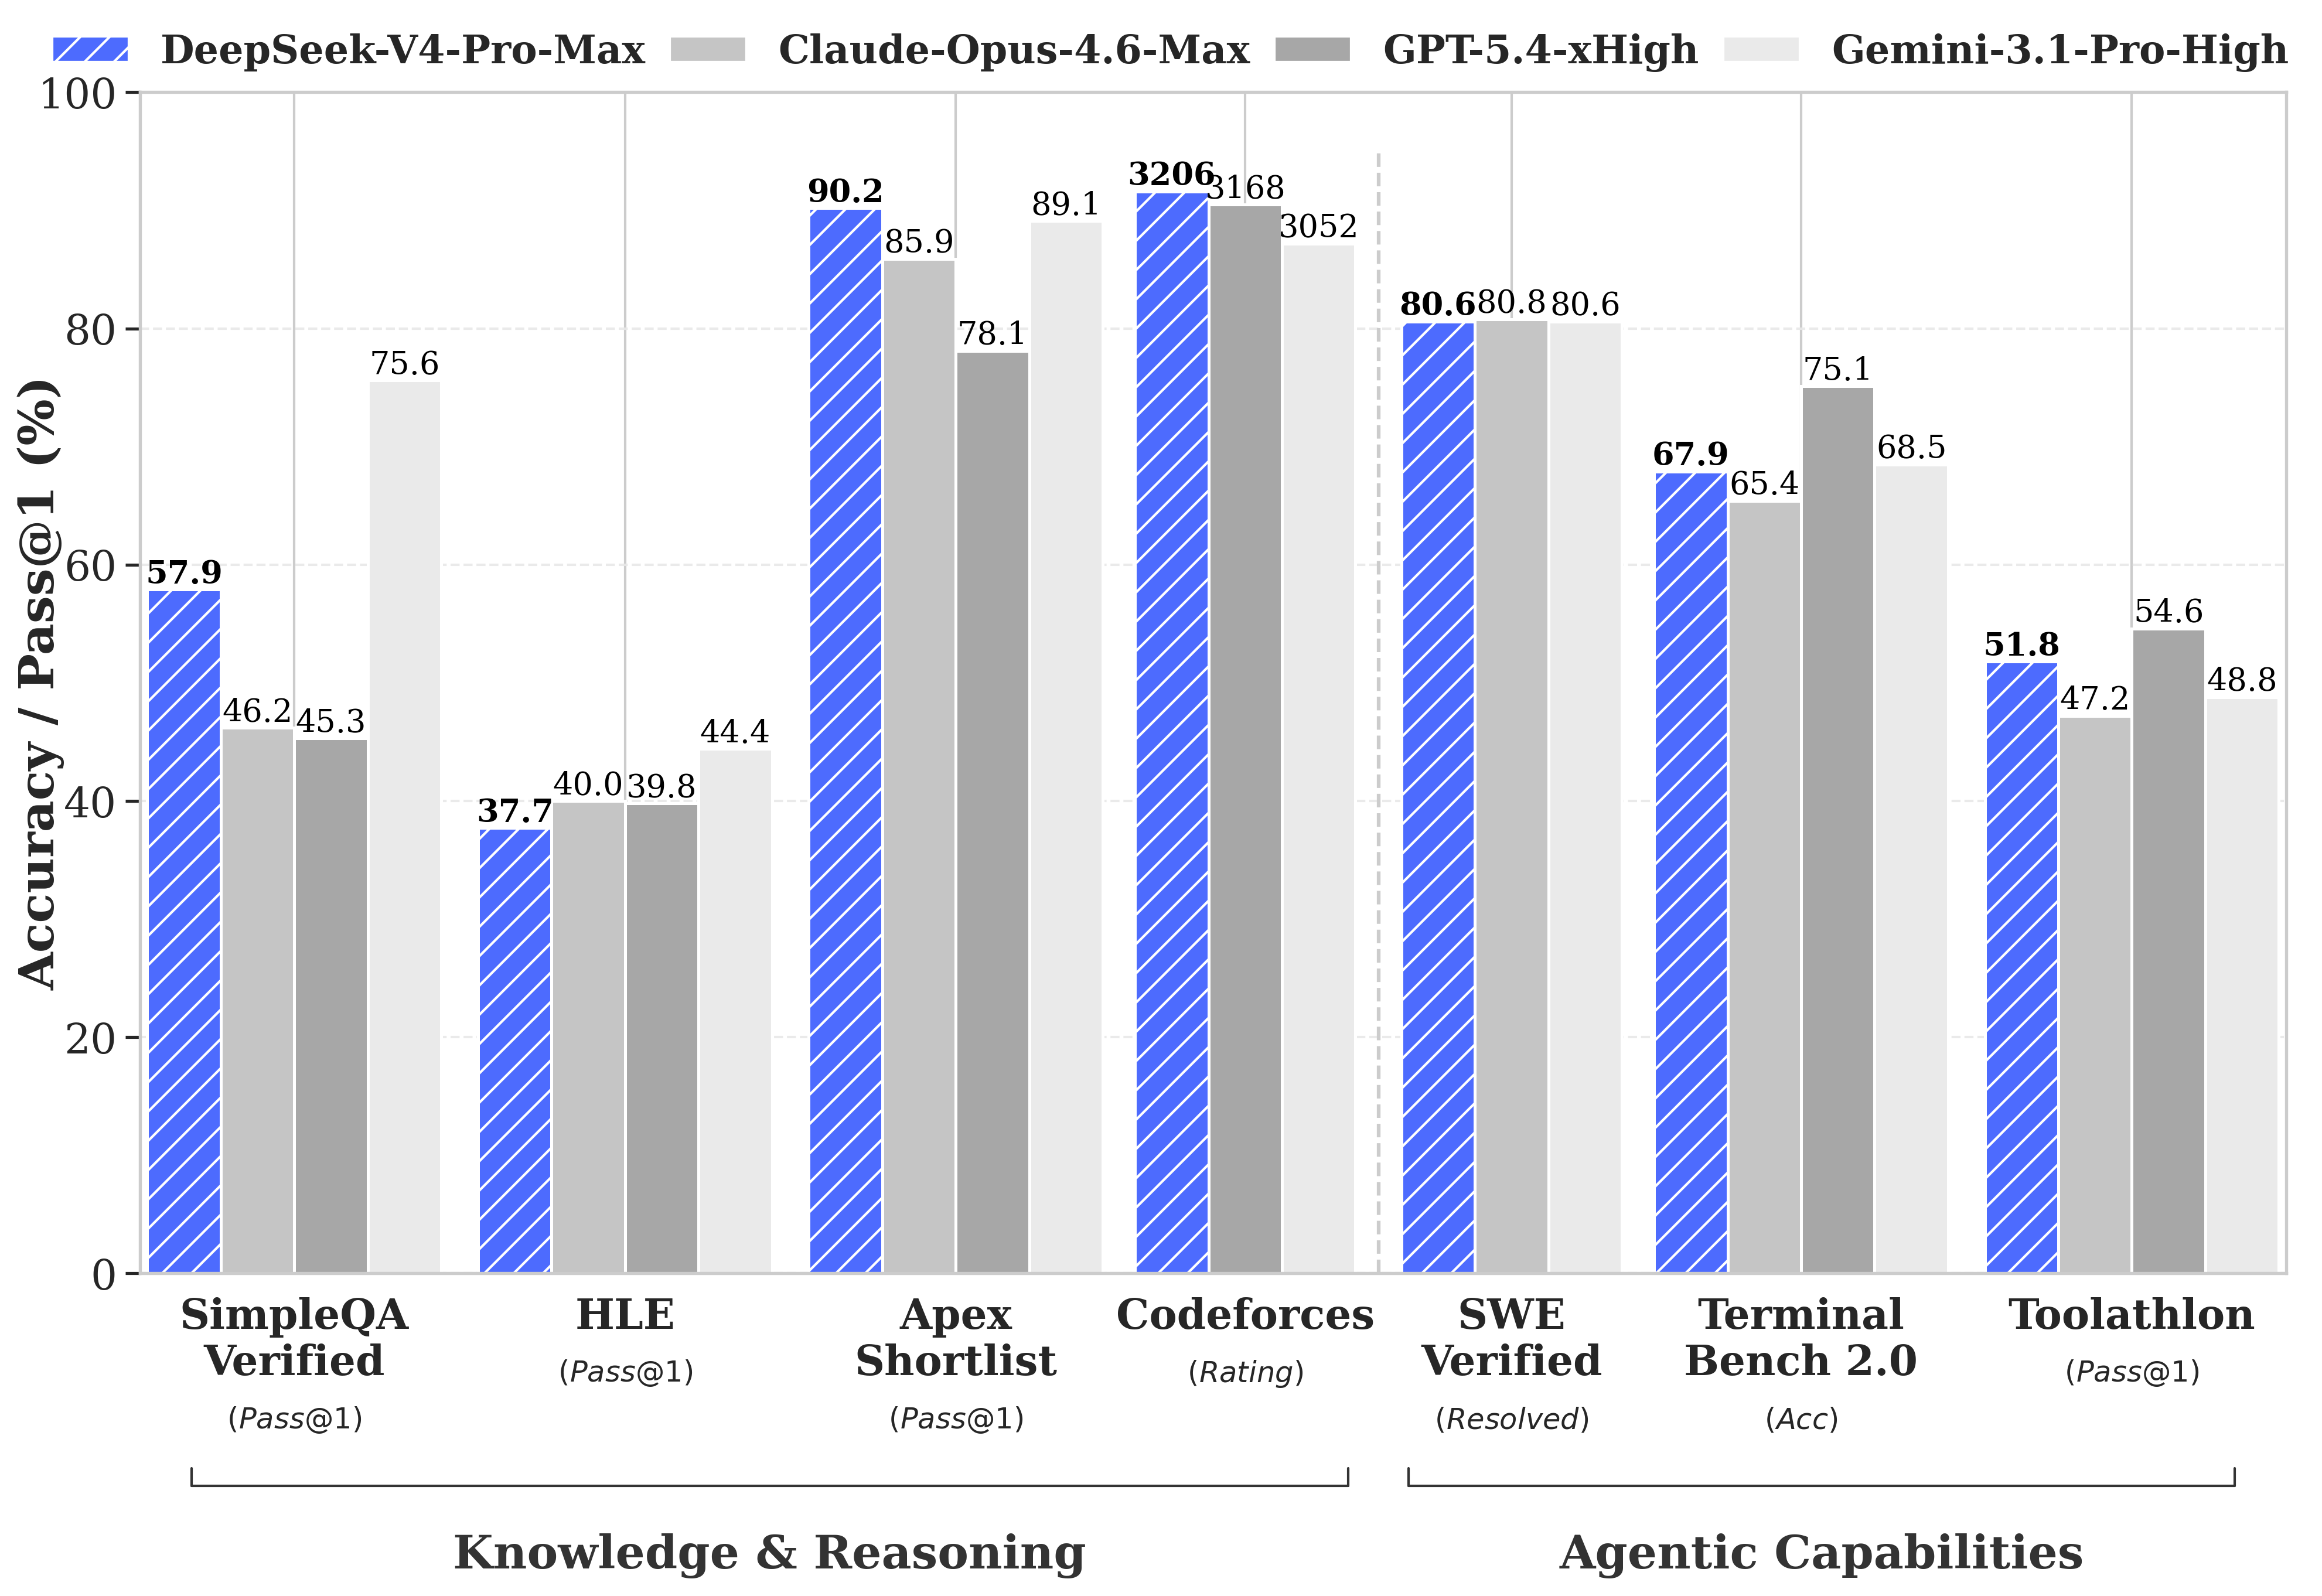
DeepSeek V4 Pro is positioned as the strongest version of the model family and focuses on corporate usage scenarios especially. Advanced reasoning capabilities, long context management and high accuracy rates make this version ideal for projects requiring large data processing.
One of the most important features of the Pro version can produce more consistent results in complex tasks. Very step-by-step problem solving, advanced level code production and analytical tasks, the performance of the model is prominent. Furthermore, thanks to the flexible structure offered via the API, companies can integrate the model according to their needs.
DeepSeek V4 Flash vs Pro: Performance and Cost Balance
Flash and Pro versions included in the DeepSeek V4 family are positioned to address different usage scenarios. Flash version, while offering lower latency and cost advantage; Pro version is working with maximum performance and accuracy.
Flash model is optimized for real-time apps like chatbots, customer service and fast content production. The corresponding Pro model is preferred in heavier and complex tasks. This distinction allows developers to choose the right model according to their needs.
Flash model offers lower latency thanks to its smaller active parameter structure compared to Pro version, while simple agent tasks can perform close to Pro level. The opposite Pro model is particularly complex reasoning, clear search for coding and scientific problem solving tasks stronger results produce.
DeepSeek V4 API Pricing: Competitive Strategy
DeepSeek V4 API pricing is evaluated as a aggressive competition strategy when considering the technical capacity of the model. Due to its MoE architecture, the reduced processing costs are reflected as a more affordable API experience to the user.
This situation stands out as a factor that directly affects the competition with large players such as OpenAI and Google in the market. Longer context, lower cost and high performance combination makes DeepSeek a strong position in global AI race.
DeepSeek V4 API works with OpenAI ChatCompletions and Anthropic compatible structure. Users only have the model name deepseek-v4-pro or deepseek-v4-flash It can integrate into existing systems by changing. Home “thinking mode” and support different reasoning levels such as “non-thinking mode”.
New Balance in Global Artificial Intelligence Race
The introduction of DeepSeek V4 is not only a technical development, but also creates a new balance point in global AI competition. The rapid progression in this area of China-based companies is becoming more angry with US-based technology giants.
In this context, the performance of models developed on NVIDIA infrastructures is also remarkable. Optimisation of hardware and software integration is among factors that play a decisive role in the future of AI.
Scale, Efficiency and Future Perspective
DeepSeek V4 is considered not only larger models in artificial intelligence; more efficient, scalable and more accessible systems as a messenger of a new era. 1 million token context capacity, 1.6 trillion parameter and advanced architectural optimizations; this model only shows that this model will shape artificial intelligence standards in the coming years.
This development reveals not only for technology companies of artificial intelligence; once it becomes a strategic infrastructure for all sectors. Together with DeepSeek V4, the “biger model” concept replaces “more intelligent and efficient model” paradigne.
DeepSeek V4, especially in global artificial intelligence race an important breaking point on the open source side create. The publication of the model with open weights strengthens the potential of creating an alternative ecosystem to closed systems.
JP Morgan Raporu: İnsansı Robotlarda Dönüm Noktası
Robotlara Beyin Geldi: Gemini Robotics-ER 1.6 ile Tanışın!


